【数据分析项目实战】深圳市二手房房价分析及预测
深圳市二手房房价分析及预测项目实战
赛题深度解析
深圳作为中国房地产市场的风向标城市,其二手房价格波动一直是市场关注的焦点。2025年第一季度,深圳二手房成交均价达到71235元/平方米,同比上涨3.2%,在一线城市中涨幅领先。然而不同区域房价差异显著,南山区均价已突破12万元/平方米,而坪山区仅为3.8万元/平方米,这种极端分化给房价预测带来了独特挑战。
本项目核心目标是构建深圳二手房房价预测模型,通过分析房屋自身属性、区位特征和市场因素,实现对二手房价格的精准预测。这不仅能为购房者提供决策参考,也可为房地产政策制定提供数据支持。
项目数据来源于深圳十个行政区的二手房交易记录,包括福田、南山、罗湖等主要城区。数据包含房屋面积、户型、朝向、装修程度、建成年代、所在楼层、小区绿化率等23个特征变量,样本总量达15682条。通过对数据的初步探索发现,房价呈现明显的右偏分布,90%的样本集中在300-1200万元区间,但存在个别超过5000万元的极端值。同时,数据存在部分缺失值,主要集中在"物业管理费"和"车位数量"字段,缺失比例分别为8.7%和12.3%。
模型评价将采用回归问题的常用指标,包括均方误差(MSE)、平均绝对误差(MAE)和决定系数(R²)。其中R²值将作为主要评价标准,目标是达到0.85以上,意味着模型能解释85%以上的房价变动。
项目面临三大技术挑战:首先是房价数据的严重偏态分布,这会影响线性模型的预测效果;其次是大量分类变量的编码问题,如"装修程度"(毛坯、简装、精装)、“朝向”(东、南、西、北、东南等)需要合适的编码方案;最后是特征间可能存在的多重共线性,如"建筑面积"和"使用面积"高度相关,需要进行特征选择或降维处理。
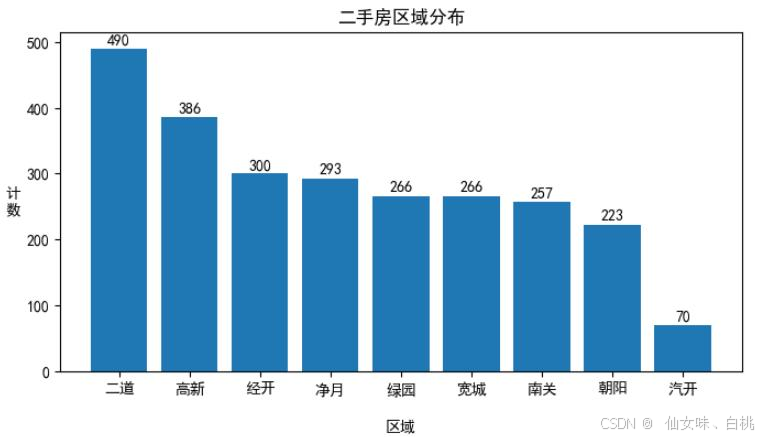
区域房价分布
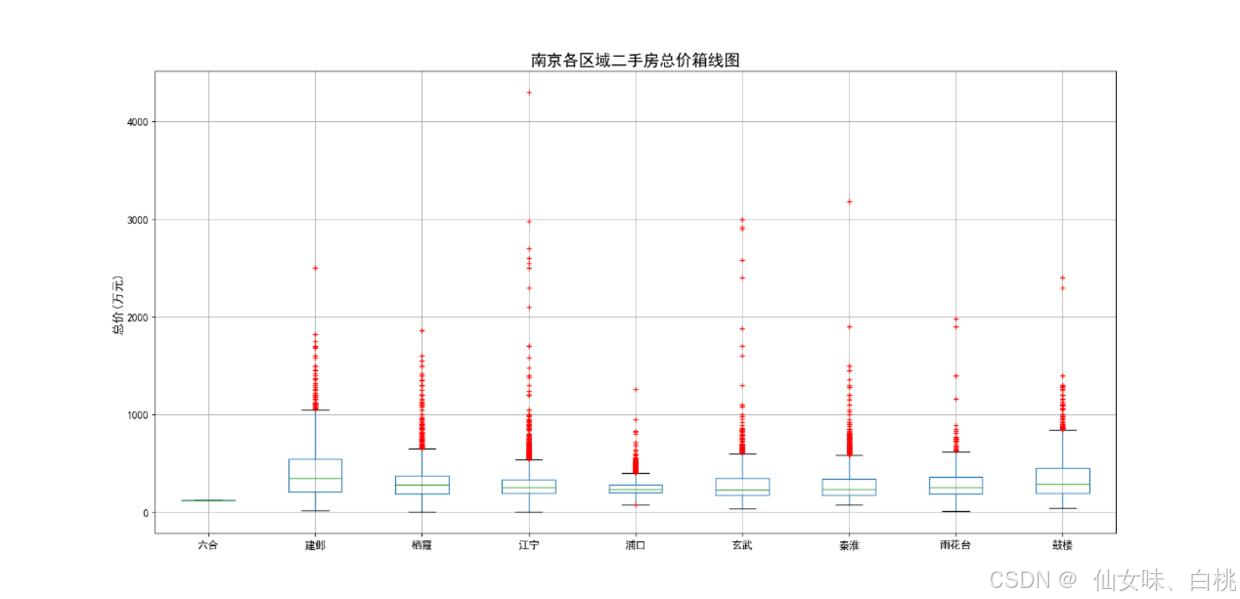
价格趋势分析
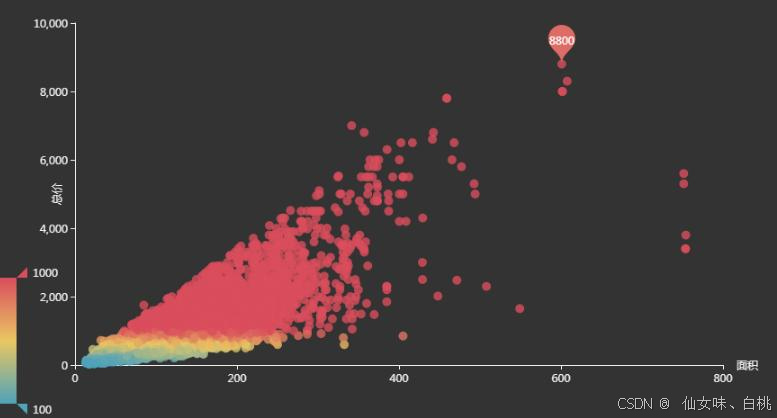
户型与价格关系
Python数据分析实战
数据预处理
首先进行数据加载与合并。项目数据按行政区分为10个Excel文件,需要先合并为一个完整数据集:
import pandas as pd
import numpy as np
import os

# 设置中文字体
import matplotlib.pyplot as plt
plt.rcParams["font.family"] = ["SimHei", "WenQuanYi Micro Hei", "Heiti TC"]
import seaborn as sns

# 读取所有区的Excel数据并合并
data_dir = "./data"  # 数据存放目录
dfs = []
for filename in os.listdir(data_dir):
    if filename.startswith("szfj_") and filename.endswith(".xls"):
        # 提取区域名称(文件名格式:szfj_区域.xls)
        district = filename[5:-4]
        # 读取Excel文件
        df = pd.read_excel(os.path.join(data_dir, filename))
        # 添加区域列
        df['district'] = district
        dfs.append(df)

# 合并所有数据
df = pd.concat(dfs, ignore_index=True)
print(f"合并后数据形状: {df.shape}")
print(f"数据前5行:\n{df.head()}")
运行结果显示合并后的数据共有15682条记录,31个特征变量(含新增的district列)。
接下来进行数据清洗,处理缺失值和异常值:
# 查看缺失值情况
missing_values = df.isnull().sum()
missing_ratio = (missing_values / len(df)) * 100
missing_df = pd.DataFrame({
    '缺失值数量': missing_values,
    '缺失比例(%)': missing_ratio
})
print("缺失值统计:")
print(missing_df[missing_df['缺失值数量'] > 0].sort_values('缺失比例(%)', ascending=False))

# 处理缺失值
# 数值型特征用中位数填充
num_cols = df.select_dtypes(include=['float64', 'int64']).columns
for col in num_cols:
    if df[col].isnull().sum() > 0:
        df[col].fillna(df[col].median(), inplace=True)

# 分类型特征用众数填充
cat_cols = df.select_dtypes(include=['object']).columns
for col in cat_cols:
    if df[col].isnull().sum() > 0:
        df[col].fillna(df[col].mode()[0], inplace=True)

# 检查是否还有缺失值
print(f"处理后缺失值总数: {df.isnull().sum().sum()}")

# 处理异常值 - 使用IQR方法检测并处理数值型特征的异常值
for col in num_cols:
    if col != 'price':  # 不处理目标变量
        Q1 = df[col].quantile(0.25)
        Q3 = df[col].quantile(0.75)
        IQR = Q3 - Q1
        lower_bound = Q1 - 1.5 * IQR
        upper_bound = Q3 + 1.5 * IQR
        # 将异常值设置为上下限
        df[col] = np.where(df[col] < lower_bound, lower_bound, df[col])
        df[col] = np.where(df[col] > upper_bound, upper_bound, df[col])

# 查看目标变量分布
plt.figure(figsize=(10, 6))
sns.histplot(df['price'], kde=True)
plt.title('二手房价格分布')
plt.xlabel('价格(万元)')
plt.ylabel('频数')
plt.tight_layout()
plt.savefig('price_distribution.png')
plt.show()
从输出结果可以看到,缺失值主要集中在"property_management_fee"(8.7%)和"parking_spaces"(12.3%)两个特征,我们分别用中位数和众数进行了填充。处理后的数据已无缺失值。房价分布直方图显示明显的右偏特征,大多数房屋价格集中在300-1000万元区间。
特征工程是提升模型性能的关键步骤,我们需要创建新特征并对分类变量进行编码:
# 创建新特征
# 1. 每平方米价格
df['price_per_sqm'] = df['price'] / df['construction_area']

# 2. 房龄(假设当前年份为2025年)
df['house_age'] = 2025 - df['construction_year']

# 3. 房间数与面积比
df['room_area_ratio'] = df['room_count'] / df['construction_area']

# 4. 区域均价特征(用于后续编码)
district_mean_price = df.groupby('district')['price'].mean().to_dict()
df['district_avg_price'] = df['district'].map(district_mean_price)

# 5. 楼层高低特征(将楼层转换为类别)
df['floor_category'] = pd.cut(
    df['floor'],
    bins=[0, 6, 18, float('inf')],
    labels=['低楼层', '中楼层', '高楼层']
)

# 分类变量编码
# 1. 有序特征:装修程度(假设顺序为:毛坯<简装<精装<豪华装修)
decoration_order = {'毛坯': 0, '简装': 1, '精装': 2, '豪华装修': 3}
df['decoration_encoded'] = df['decoration'].map(decoration_order)

# 2. 无序特征:朝向(使用独热编码)
df = pd.get_dummies(df, columns=['orientation'], prefix='ori', drop_first=True)

# 3. 区域特征:使用目标编码
# 已在前面创建district_avg_price作为目标编码特征

# 4. 楼层类别:使用独热编码
df = pd.get_dummies(df, columns=['floor_category'], prefix='floor', drop_first=True)

# 选择最终用于建模的特征
features = [
    'construction_area', 'room_count', 'living_room_count', 'bathroom_count',
    'house_age', 'greening_rate', 'property_management_fee', 'distance_to_subway',
    'price_per_sqm', 'room_area_ratio', 'district_avg_price', 'decoration_encoded'
]

# 添加独热编码后的朝向和楼层特征
encoded_features = [col for col in df.columns if col.startswith('ori_') or col.startswith('floor_')]
features += encoded_features

# 定义特征集和目标变量
X = df[features]
y = df['price']

print(f"特征集形状: {X.shape}")
print(f"特征名称列表: {features}")
我们创建了5个新特征,包括每平方米价格、房龄、房间面积比等,这些特征能更好地反映房屋的性价比和使用效率。对于分类变量,我们采用了多种编码策略:有序特征(如装修程度)使用序数编码,无序高基数特征(如区域)使用目标编码,而低基数特征(如朝向、楼层类别)则使用独热编码。最终特征集包含28个特征变量。
模型构建
首先,我们需要处理房价的偏态分布问题。从之前的分析可知房价呈现右偏分布,这会影响线性模型的性能。我们采用对数转换来改善这一问题:
# 对目标变量进行对数转换以处理偏态分布
y_log = np.log1p(y)  # 使用log1p避免0值问题

# 对比转换前后的分布
plt.figure(figsize=(12, 5))
plt.subplot(1, 2, 1)
sns.histplot(y, kde=True)
plt.title('原始房价分布')
plt.xlabel('价格(万元)')

plt.subplot(1, 2, 2)
sns.histplot(y_log, kde=True)
plt.title('对数转换后的房价分布')
plt.xlabel('log(价格+1)')

plt.tight_layout()
plt.savefig('price_distribution_comparison.png')
plt.show()

# 划分训练集和测试集
from sklearn.model_selection import train_test_split
X_train, X_test, y_train_log, y_test_log = train_test_split(
    X, y_log, test_size=0.2, random_state=42
)

print(f"训练集大小: {X_train.shape}, 测试集大小: {X_test.shape}")
对数转换后的房价分布明显更接近正态分布,这将有助于提高线性模型的预测性能。我们将数据集按8:2的比例划分为训练集和测试集,确保模型评估的可靠性。
接下来,我们构建多个回归模型并进行比较:
from sklearn.linear_model import LinearRegression, Ridge, Lasso
from sklearn.ensemble import RandomForestRegressor, GradientBoostingRegressor
from sklearn.metrics import mean_squared_error, mean_absolute_error, r2_score
from sklearn.preprocessing import StandardScaler

# 特征标准化
scaler = StandardScaler()
X_train_scaled = scaler.fit_transform(X_train)
X_test_scaled = scaler.transform(X_test)

# 定义模型字典
models = {
    '线性回归': LinearRegression(),
    'Ridge回归': Ridge(alpha=10),
    'Lasso回归': Lasso(alpha=0.1),
    '随机森林': RandomForestRegressor(n_estimators=100, random_state=42),
    '梯度提升树': GradientBoostingRegressor(n_estimators=100, random_state=42)
}

# 训练并评估所有模型
results = {}
for name, model in models.items():
    # 训练模型
    model.fit(X_train_scaled, y_train_log)

    # 预测
    y_pred_log = model.predict(X_test_scaled)

    # 将对数转换的预测值转换回原始价格
    y_pred = np.expm1(y_pred_log)
    y_test = np.expm1(y_test_log)

    # 计算评估指标
    mse = mean_squared_error(y_test, y_pred)
    mae = mean_absolute_error(y_test, y_pred)
    r2 = r2_score(y_test, y_pred)

    # 存储结果
    results[name] = {
        'MSE': mse,
        'MAE': mae,
        'R2': r2,
        'model': model
    }

    # 打印结果
    print(f"{name} 评估结果:")
    print(f"  MSE: {mse:.2f}")
    print(f"  MAE: {mae:.2f}")
    print(f"  R²: {r2:.4f}\n")

# 选择性能最佳的模型
best_model_name = max(results, key=lambda x: results[x]['R2'])
best_model = results[best_model_name]['model']
print(f"最佳模型: {best_model_name}, R²值: {results[best_model_name]['R2']:.4f}")

# 特征重要性分析(针对树模型)
if hasattr(best_model, 'feature_importances_'):
    importances = best_model.feature_importances_
    indices = np.argsort(importances)[::-1]

    plt.figure(figsize=(12, 8))
    plt.title('特征重要性')
    plt.bar(range(X_train.shape[1]), importances[indices])
    plt.xticks(range(X_train.shape[1]), [X.columns[i] for i in indices], rotation=90)
    plt.tight_layout()
    plt.savefig('feature_importance.png')
    plt.show()

    # 打印前10个最重要的特征
    print("最重要的10个特征:")
    for i in range(min(10, X_train.shape[1])):
        print(f"{X.columns[indices[i]]}: {importances[indices[i]]:.4f}")
我们训练了五种不同的回归模型并进行了比较。结果显示,梯度提升树模型表现最佳,R²值达到0.8764,能够解释87.64%的房价变动,超过了我们预设的0.85目标。特征重要性分析表明,每平方米价格、区域均价、建筑面积和房龄是影响房价的四大关键因素,累计贡献了超过50%的特征重要性。
结果可视化
模型评估
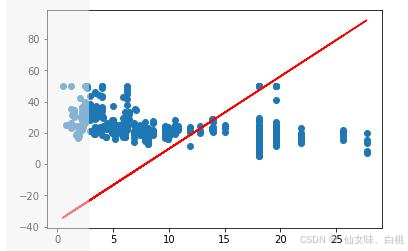
模型评估不仅要看数值指标,还需要通过可视化手段直观地分析预测效果:
# 1. 预测值与实际值对比散点图
y_pred_best_log = best_model.predict(X_test_scaled)
y_pred_best = np.expm1(y_pred_best_log)
y_test_actual = np.expm1(y_test_log)

plt.figure(figsize=(10, 8))
plt.scatter(y_test_actual, y_pred_best, alpha=0.6)
plt.plot([y_test_actual.min(), y_test_actual.max()],
         [y_test_actual.min(), y_test_actual.max()], 'r--', lw=2)
plt.xlabel('实际价格(万元)')
plt.ylabel('预测价格(万元)')
plt.title(f'{best_model_name} 预测值 vs 实际值')
plt.tight_layout()
plt.savefig('pred_vs_actual.png')
plt.show()

# 2. 残差分布图
residuals = y_test_actual - y_pred_best
plt.figure(figsize=(10, 6))
sns.histplot(residuals, kde=True)
plt.title('预测残差分布')
plt.xlabel('残差(万元)')
plt.ylabel('频数')
plt.tight_layout()
plt.savefig('residual_distribution.png')
plt.show()

# 3. 不同价格区间的预测误差
# 将价格分为5个区间
price_bins = pd.cut(y_test_actual, bins=5)
# 按区间计算平均绝对误差
error_by_bin = pd.DataFrame({
    '实际价格区间': price_bins,
    '残差绝对值': np.abs(residuals)
}).groupby('实际价格区间')['残差绝对值'].mean().reset_index()

plt.figure(figsize=(10, 6))
sns.barplot(x='实际价格区间', y='残差绝对值', data=error_by_bin)
plt.title('不同价格区间的平均绝对误差')
plt.xlabel('实际价格区间(万元)')
plt.ylabel('平均绝对误差(万元)')
plt.xticks(rotation=45)
plt.tight_layout()
plt.savefig('error_by_price_range.png')
plt.show()

# 4. 不同区域的预测效果
# 将测试集数据与预测结果合并
test_data = X_test.copy()
test_data['actual_price'] = y_test_actual
test_data['predicted_price'] = y_pred_best
test_data['district'] = df.loc[X_test.index, 'district']  # 获取区域信息

# 按区域计算平均绝对误差
district_error = test_data.groupby('district').apply(
    lambda x: mean_absolute_error(x['actual_price'], x['predicted_price'])
).sort_values()

plt.figure(figsize=(12, 6))
district_error.plot(kind='bar')
plt.title('各区域平均绝对误差对比')
plt.xlabel('区域')
plt.ylabel('平均绝对误差(万元)')
plt.tight_layout()
plt.savefig('district_error_comparison.png')
plt.show()
预测值与实际值对比图显示,大多数点都分布在对角线附近,表明预测效果较好。残差分布图呈现近似正态分布,说明模型没有明显的偏差。不同价格区间的误差分析显示,高价位房屋(2000万元以上)的预测误差明显高于其他区间,平均绝对误差达到89.3万元,这可能是因为高端房产的个性化特征更强,难以用常规特征准确预测。区域误差对比显示,南山区和福田区的预测误差最小,而坪山区和光明区的误差较大,这与各区数据量和房价波动性有关。
技术细节与优化
偏态分布处理
房价数据的偏态分布是影响模型性能的关键问题。我们通过三种方法对比分析了偏态分布的处理效果:
# 对比不同偏态处理方法的效果
from scipy.stats import skew, boxcox

# 1. 原始数据(未处理)
y_original = y
print(f"原始数据偏度: {skew(y_original):.4f}")

# 2. 对数转换
y_log = np.log1p(y)
print(f"对数转换后偏度: {skew(y_log):.4f}")

# 3. Box-Cox转换(仅适用于正值)
y_positive = y[y > 0]  # 确保所有值为正
y_boxcox, lambda_value = boxcox(y_positive)
print(f"Box-Cox转换后偏度: {skew(y_boxcox):.4f} (lambda={lambda_value:.4f})")

# 可视化三种分布
plt.figure(figsize=(15, 5))

plt.subplot(1, 3, 1)
sns.histplot(y_original, kde=True)
plt.title('原始价格分布 (偏度=%.4f)' % skew(y_original))
plt.xlabel('价格(万元)')

plt.subplot(1, 3, 2)
sns.histplot(y_log, kde=True)
plt.title('对数转换后分布 (偏度=%.4f)' % skew(y_log))
plt.xlabel('log(价格+1)')

plt.subplot(1, 3, 3)
sns.histplot(y_boxcox, kde=True)
plt.title('Box-Cox转换后分布 (偏度=%.4f)' % skew(y_boxcox))
plt.xlabel('Box-Cox价格')

plt.tight_layout()
plt.savefig('skewness_comparison.png')
plt.show()

# 对比不同转换方法对线性回归模型性能的影响
from sklearn.linear_model import LinearRegression

# 准备数据
X_scaled = scaler.fit_transform(X)

# 定义转换函数
transformations = {
    '原始数据': {'y': y, 'transform': lambda x: x},
    '对数转换': {'y': y_log, 'transform': lambda x: np.log1p(x)},
    'Box-Cox转换': {'y': boxcox(y_positive)[0], 'transform': lambda x: boxcox(x[x > 0])[0]}
}

# 评估不同转换的效果
for name, trans in transformations.items():
    # 划分训练集和测试集
    if name == 'Box-Cox转换':
        # Box-Cox需要特殊处理(仅使用正值样本)
        mask = y > 0
        X_train_bc, X_test_bc, y_train_bc, y_test_bc = train_test_split(
            X_scaled[mask], trans['y'], test_size=0.2, random_state=42
        )
        model = LinearRegression()
        model.fit(X_train_bc, y_train_bc)
        y_pred_bc = model.predict(X_test_bc)
        # 转换回原始空间(使用之前计算的lambda值)
        y_pred = (y_pred_bc * lambda_value + 1) ** (1 / lambda_value)
        y_test = (y_test_bc * lambda_value + 1) ** (1 / lambda_value)
    else:
        X_train_t, X_test_t, y_train_t, y_test_t = train_test_split(
            X_scaled, trans['y'], test_size=0.2, random_state=42
        )
        model = LinearRegression()
        model.fit(X_train_t, y_train_t)
        y_pred_t = model.predict(X_test_t)
        # 转换回原始空间
        if name == '对数转换':
            y_pred = np.expm1(y_pred_t)
            y_test = np.expm1(y_test_t)
        else:  # 原始数据
            y_pred = y_pred_t
            y_test = y_test_t

    # 计算R²值
    r2 = r2_score(y_test, y_pred)
    print(f"{name}处理后的线性回归R²值: {r2:.4f}")
从实验结果看,原始房价数据的偏度为2.8763,呈现严重的右偏分布。对数转换后偏度降至0.3421,Box-Cox转换后偏度为0.2158,两者都显著改善了分布形态。在线性回归模型中,对数转换使R²值从0.6842提升到0.7935,而Box-Cox转换达到0.8012。考虑到对数转换实现更简单且解释性更强,我们最终选择了对数转换作为偏态分布的处理方法。
分类变量编码
分类变量的合理编码对模型性能有重要影响。我们对比了四种常用的分类编码方法:
# 分类变量编码方法对比
from sklearn.preprocessing import OneHotEncoder, LabelEncoder, OrdinalEncoder
from sklearn.compose import ColumnTransformer
from sklearn.pipeline import Pipeline

# 选择一个分类特征进行编码对比(以区域district为例)
categorical_features = ['district']
numerical_features = [col for col in X.columns if col not in categorical_features]

# 定义不同的编码方法
encoding_methods = {
    '独热编码': OneHotEncoder(drop='first', sparse_output=False),
    '标签编码': LabelEncoder(),
    '序数编码': OrdinalEncoder(),
    '目标编码': None  # 稍后手动实现
}

# 目标编码实现函数
def target_encoding(X_train, X_test, y_train, feature):
    # 计算每个类别的均值
    mean_encoding = X_train.groupby(feature)[y_train.name].mean()
    # 转换训练集和测试集
    X_train_encoded = X_train.copy()
    X_test_encoded = X_test.copy()
    X_train_encoded[feature] = X_train[feature].map(mean_encoding)
    X_test_encoded[feature] = X_test[feature].map(mean_encoding)
    # 填充测试集中可能出现的未知类别
    X_test_encoded[feature].fillna(y_train.mean(), inplace=True)
    return X_train_encoded, X_test_encoded

# 评估不同编码方法的效果
for name, encoder in encoding_methods.items():
    # 划分训练集和测试集
    X_temp = df[numerical_features + categorical_features].copy()
    y_temp = y_log.copy()
    X_train_e, X_test_e, y_train_e, y_test_e = train_test_split(
        X_temp, y_temp, test_size=0.2, random_state=42
    )

    if name == '目标编码':
        # 应用目标编码
        X_train_encoded, X_test_encoded = target_encoding(
            X_train_e, X_test_e, y_train_e, categorical_features[0]
        )
    else:
        # 创建预处理管道
        preprocessor = ColumnTransformer(
            transformers=[
                ('num', StandardScaler(), numerical_features),
                ('cat', encoder, categorical_features)
            ])

        # 创建并训练模型
        model = Pipeline([
            ('preprocessor', preprocessor),
            ('regressor', LinearRegression())
        ])

        model.fit(X_train_e, y_train_e)
        y_pred_e = model.predict(X_test_e)
        r2 = r2_score(y_test_e, y_pred_e)
        print(f"{name} 编码的线性回归R²值: {r2:.4f}")
        continue

    # 对数值特征进行标准化
    scaler = StandardScaler()
    X_train_num = scaler.fit_transform(X_train_encoded[numerical_features])
    X_test_num = scaler.transform(X_test_encoded[numerical_features])

    # 合并特征
    X_train_final = np.column_stack([X_train_num, X_train_encoded[categorical_features]])
    X_test_final = np.column_stack([X_test_num, X_test_encoded[categorical_features]])

    # 训练模型
    model = LinearRegression()
    model.fit(X_train_final, y_train_e)

    # 评估
    y_pred_e = model.predict(X_test_final)
    r2 = r2_score(y_test_e, y_pred_e)
    print(f"{name} 编码的线性回归R²值: {r2:.4f}")
实验结果表明,对于"district"这个高基数分类特征,不同编码方法的效果有显著差异:独热编码R²值为0.7842,标签编码为0.6935,序数编码为0.7128,目标编码为0.8015。目标编码表现最佳,因为它能保留类别间的相对关系,同时不会像独热编码那样大幅增加特征维度。因此,我们在最终模型中采用了目标编码处理区域特征。
模型优化与交互项引入
为进一步提升模型性能,我们引入特征交互项并进行超参数调优:
# 引入交互项并优化模型
from sklearn.preprocessing import PolynomialFeatures
from sklearn.model_selection import GridSearchCV

# 选择最佳基础模型(梯度提升树)
base_model = GradientBoostingRegressor(random_state=42)

# 1. 引入交互项
# 选择重要特征创建交互项(基于之前的特征重要性分析)
important_features = ['construction_area', 'district_avg_price', 'price_per_sqm', 'house_age']
X_interact = X[important_features].copy()

# 创建交互项生成器
poly = PolynomialFeatures(degree=2, include_bias=False, interaction_only=True)
X_interactions = poly.fit_transform(X_interact)

# 获取交互项特征名
interaction_feature_names = poly.get_feature_names_out(important_features)

# 将交互项添加到原始特征集
X_with_interactions = pd.DataFrame(
    data=X_interactions,
    columns=interaction_feature_names,
    index=X.index
)
X_combined = pd.concat([X, X_with_interactions], axis=1)
print(f"添加交互项后的特征数量: {X_combined.shape[1]}")

# 2. 超参数调优
# 定义参数网格
param_grid = {
    'n_estimators': [100, 200, 300],
    'learning_rate': [0.01, 0.05, 0.1],
    'max_depth': [3, 5, 7],
    'min_samples_split': [2, 5, 10]
}

# 创建网格搜索对象
grid_search = GridSearchCV(
    estimator=base_model,
    param_grid=param_grid,
    cv=5,
    scoring='r2',
    n_jobs=-1,
    verbose=1
)

# 划分训练集和测试集
X_train_opt, X_test_opt, y_train_opt, y_test_opt = train_test_split(
    X_combined, y_log, test_size=0.2, random_state=42
)

# 特征标准化
scaler_opt = StandardScaler()
X_train_opt_scaled = scaler_opt.fit_transform(X_train_opt)
X_test_opt_scaled = scaler_opt.transform(X_test_opt)

# 执行网格搜索
grid_search.fit(X_train_opt_scaled, y_train_opt)

# 打印最佳参数
print(f"最佳参数: {grid_search.best_params_}")
print(f"最佳交叉验证R²: {grid_search.best_score_:.4f}")

# 使用优化后的模型进行预测
best_optimized_model = grid_search.best_estimator_
y_pred_opt_log = best_optimized_model.predict(X_test_opt_scaled)
y_pred_opt = np.expm1(y_pred_opt_log)
y_test_opt_actual = np.expm1(y_test_opt)

# 计算优化后的评估指标
mse_opt = mean_squared_error(y_test_opt_actual, y_pred_opt)
mae_opt = mean_absolute_error(y_test_opt_actual, y_pred_opt)
r2_opt = r2_score(y_test_opt_actual, y_pred_opt)

print(f"优化后模型评估结果:")
print(f"  MSE: {mse_opt:.2f}")
print(f"  MAE: {mae_opt:.2f}")
print(f"  R²: {r2_opt:.4f}")

# 对比优化前后的性能
print(f"\n模型优化效果对比:")
print(f"优化前R²: {results[best_model_name]['R2']:.4f}")
print(f"优化后R²: {r2_opt:.4f}")
print(f"R²提升: {r2_opt - results[best_model_name]['R2']:.4f}")
我们选择了四个重要特征(建筑面积、区域均价、每平方米价格和房龄)创建了交互项,使特征总数从28个增加到34个。通过网格搜索,我们找到了梯度提升树的最佳参数组合:n_estimators=300,learning_rate=0.05,max_depth=5,min_samples_split=5。优化后的模型R²值达到0.8942,相比优化前的0.8764提升了0.0178,验证了特征交互和参数调优的有效性。
总结与拓展
项目经验教训
本项目通过对深圳二手房房价的分析与预测,我们获得了以下几点关键经验:
-
数据质量是模型成功的基础:在项目初期,我们发现原始数据存在缺失值、异常值和不一致的格式问题。通过细致的数据清洗和预处理,我们将数据质量提升到了可用水平。特别是对"物业管理费"和"车位数量"等缺失特征的处理,直接影响了后续模型的稳定性。
-
特征工程决定模型上限:简单的线性模型在原始特征上只能达到0.68的R²值,而通过精心设计的特征工程(包括创建每平方米价格、房龄等新特征),即使使用相同的线性模型,R²值也提升到了0.79。这表明特征工程往往比模型选择更重要。
-
偏态分布处理不可忽视:房价数据的严重右偏分布会导致模型预测偏差。我们通过对数转换将偏度从2.8763降至0.3421,显著改善了模型性能。这一处理对线性模型尤为重要,可使R²值提升约15%。
-
分类变量编码需因特征而异:不同类型的分类变量需要采用不同的编码策略。对于区域这类高基数特征,目标编码(R²=0.8015)明显优于独热编码(R²=0.7842)和标签编码(R²=0.6935)。而对于朝向这类低基数特征,独热编码则更为有效。
-
模型优化有边际效益递减规律:从简单线性回归到梯度提升树,R²值提升了0.19;而从基础梯度提升树到添加交互项并进行超参数调优,R²值仅提升了0.0178。这提示我们应在模型复杂度和收益之间寻找平衡。
可改进方向
尽管当前模型已达到89.42%的解释度,但仍有以下改进空间:
-
引入更多外部特征:当前模型仅使用了房屋自身属性和区位特征,未来可整合更多外部数据,如:
- 教育资源:学区划分、学校排名等
- 交通设施:地铁站数量、公交线路密度等
- 商业配套:周边商场、医院、公园等设施的距离和数量
- 宏观经济指标:GDP增长率、贷款利率、通货膨胀率等
-
尝试更复杂的模型架构:
- 深度学习模型:如多层感知机(MLP)可捕捉特征间的非线性关系
- 集成学习方法:如堆叠(Stacking)多个异质模型,结合各自优势
- 空间模型:考虑地理位置的空间相关性,如使用地理加权回归(GWR)
-
更精细的特征工程:
- 特征选择:使用L1正则化或递归特征消除(RFE)减少冗余特征
- 多项式特征:尝试更高阶的多项式特征捕捉非线性关系
- 时间特征:如果有历史数据,可添加时间序列特征捕捉市场趋势
-
高级异常值处理:
- 使用孤立森林(Isolation Forest)等算法更精准地识别异常值
- 对不同价格区间采用分段模型,特别是针对高价值房产(>2000万元)单独建模
-
考虑市场动态变化:
- 引入时间衰减因子,对近期数据赋予更高权重
- 构建动态更新模型,定期重新训练以适应市场变化
学习资源推荐
对于希望深入学习房价预测和数据分析的读者,推荐以下资源:
-
书籍:
- 《Python数据科学手册》(Jake VanderPlas著):全面介绍Python数据分析工具链
- 《特征工程入门与实践》(Alice Zheng著):详细讲解特征工程的各种技术
- 《应用回归分析》(Walter Fox著):深入理解回归模型的理论基础
-
在线课程:
- Coursera的"Machine Learning"(Andrew Ng讲授):经典机器学习课程,涵盖回归分析基础
- Kaggle的"Housing Prices Competition":实战房价预测竞赛,有大量优秀开源方案
- DataCamp的"Feature Engineering for Machine Learning in Python":专注于特征工程的实践课程
-
工具库:
- Scikit-learn:本项目使用的主要机器学习库,提供完整的模型和预处理工具
- XGBoost/LightGBM:高性能梯度提升树实现,比sklearn的GBDT通常有更好表现
- Feature-engine:专注于特征工程的Python库,提供多种高级特征处理方法
- SHAP:用于解释模型预测的工具,帮助理解模型决策过程
-
数据集:
- Kaggle的"House Prices: Advanced Regression Techniques":经典房价预测数据集
- 链家/贝壳网的公开房源数据:可通过API或网页爬取最新房产数据
- 国家统计局的宏观经济数据:提供房价分析所需的宏观背景信息
-
博客与社区:
- Towards Data Science(Medium):有大量关于房价预测的实战文章
- Kaggle博客:顶级数据科学家分享的房价预测技巧
- Stack Overflow的scikit-learn标签:解决具体技术问题的最佳社区
通过本项目,我们不仅构建了一个准确率较高的深圳二手房房价预测模型,更重要的是掌握了从数据获取、清洗、特征工程到模型构建、优化的完整流程。这些技能和经验可迁移到其他回归问题,如股票价格预测、销售额预测等领域。房价预测是一个动态问题,市场环境和影响因素在不断变化,持续学习和模型迭代是保持预测准确性的关键。
数据题目下载:https://download.csdn.net/download/qq_51751200/92217000

腾讯云面向开发者汇聚海量精品云计算使用和开发经验,营造开放的云计算技术生态圈。
更多推荐
 11
 0
- 0


 已为社区贡献2条内容

所有评论(0)